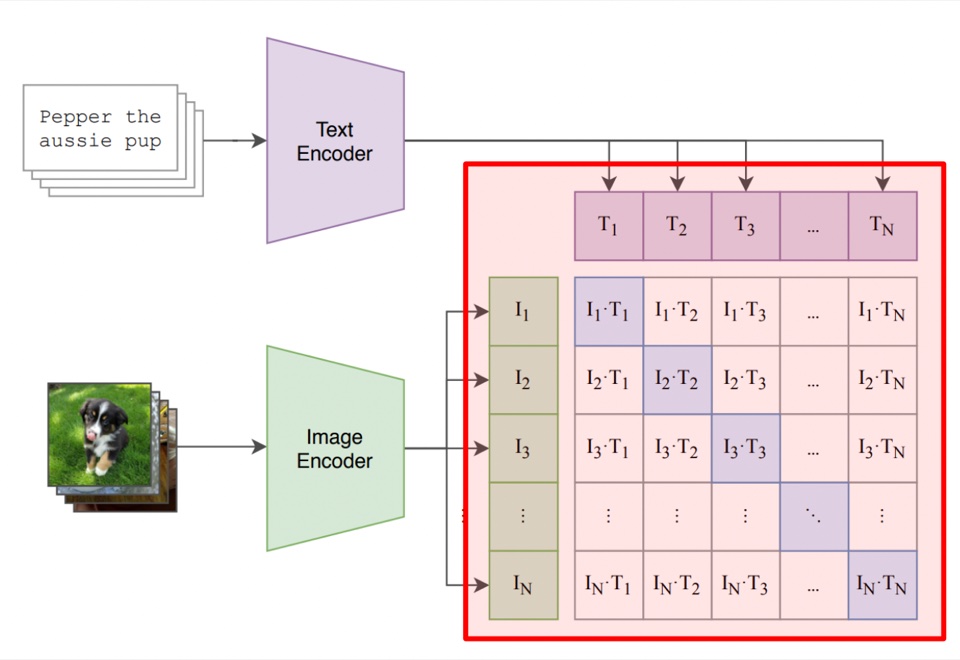
The problem. Retrieving the right radiology report for an image, or the right image for a description, helps search and report drafting. Full-size CLIP models are expensive to train and deploy, and general-domain CLIP transfers poorly to medical images.
Approach
- Model. A dual encoder: ResNet-18 for images and DistilBERT for captions, each followed by a projection into a shared 256-d embedding space.
- Training. Symmetric InfoNCE loss (temperature 0.07) on ROCO radiology image-caption pairs, starting from pretrained backbones.
- Retrieval. Embeddings indexed with FAISS for fast text-to-image and image-to-text search; runs on CUDA, Apple MPS or CPU.
Results
28% Recall@1 and 55% Recall@10 on image-text retrieval, with zero-shot classification by comparing an image against text prompts.