Yash Bhardwaj

I am a master's student in AI at École Polytechnique, interested in robot learning, representation learning, diffusion/flow matching, and multimodal LLMs. Most recently I was a research intern at Inria Paris in the Willow team, with Cordelia Schmid and Shizhe Chen, on pretraining 3D representations for vision-language-action models and downstream manipulation. Before that I worked with Georgia Tech on multimodal AI for finance and co-authored two papers in the area, at KDD 2025 (oral) and an ICCV 2025 workshop. I came to research after three and a half years as a software engineer at Urban Company.

Looking for research internships from April 2027 in reinforcement learning and robot learning, multimodal learning, diffusion/flow matching, and LLM and VLM pre- and post-training.

Affiliation École Polytechnique, IP Paris
Research Reinforcement Learning, Robot Learning, Representation Learning, World Models, Diffusion/Flow Matching, Multimodal LLMs
Selected Research

Publications

ICCV 2025

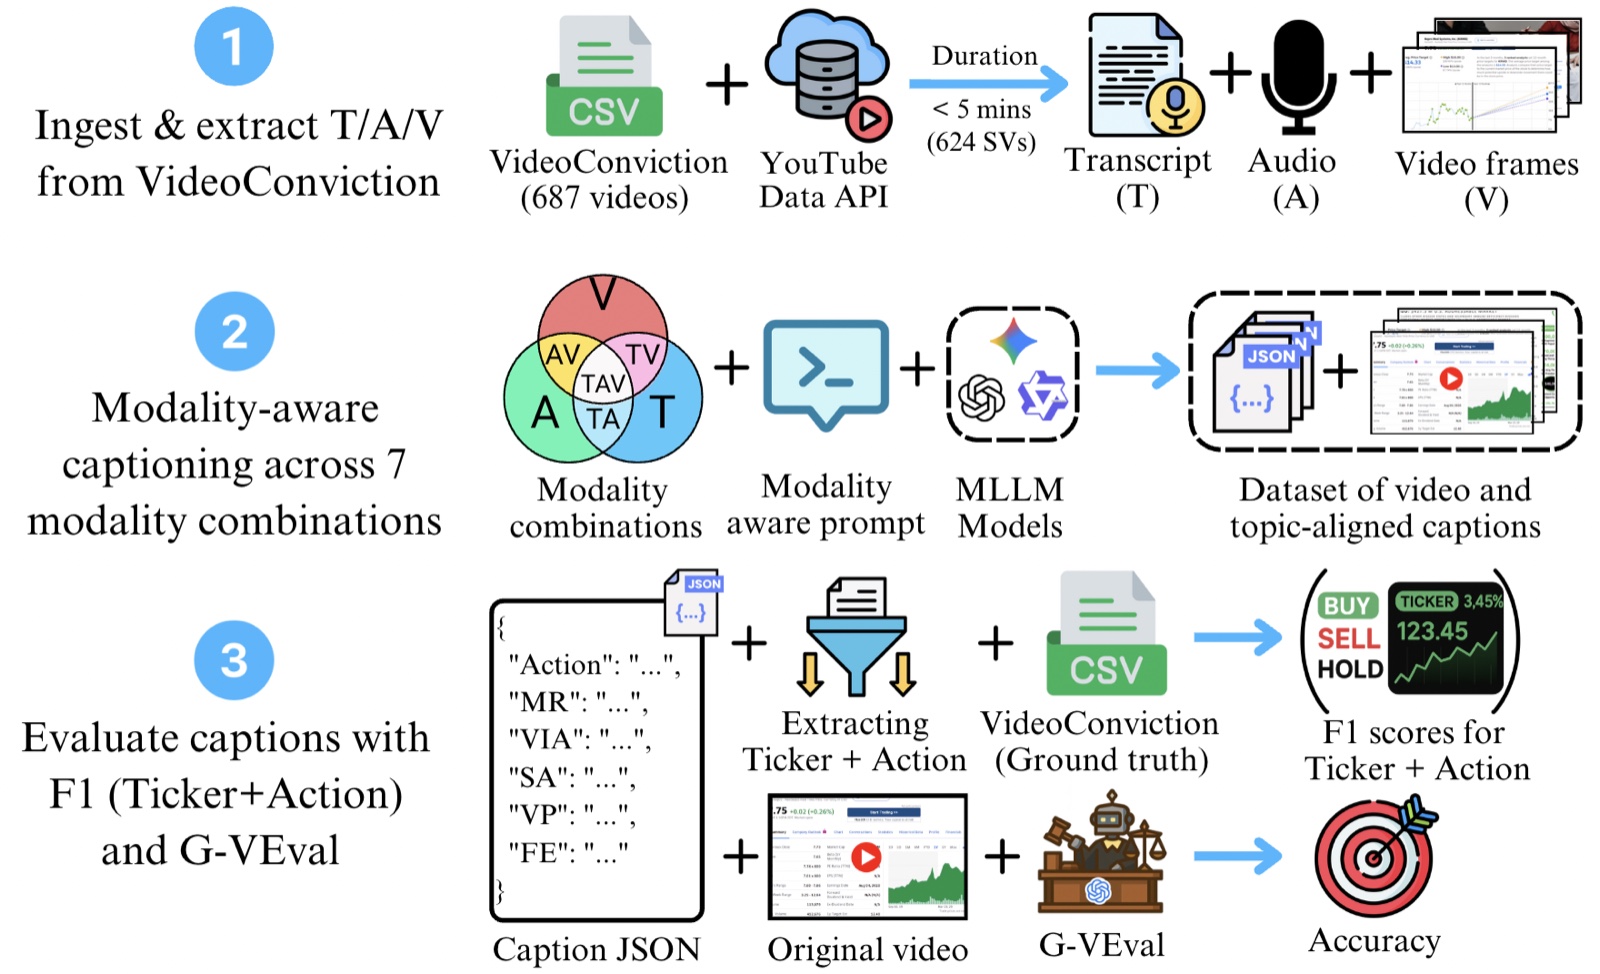
FinCap: Topic-Aligned Captions for Short-Form Financial YouTube Videos

Yash Bhardwaj*, Siddhant Sukhani*, Riya Bhadani, Veer Kejriwal, Michael Galarnyk, Sudheer Chava

The first benchmark for topic-aligned captioning of financial short videos: 624 YouTube clips, 5 topics and all 7 combinations of transcript, audio and video across 5 multimodal LLMs. Video alone is the best single input on 4 of 5 topics, while a well-chosen pair such as audio + video often beats all three.
KDD Oral 2025

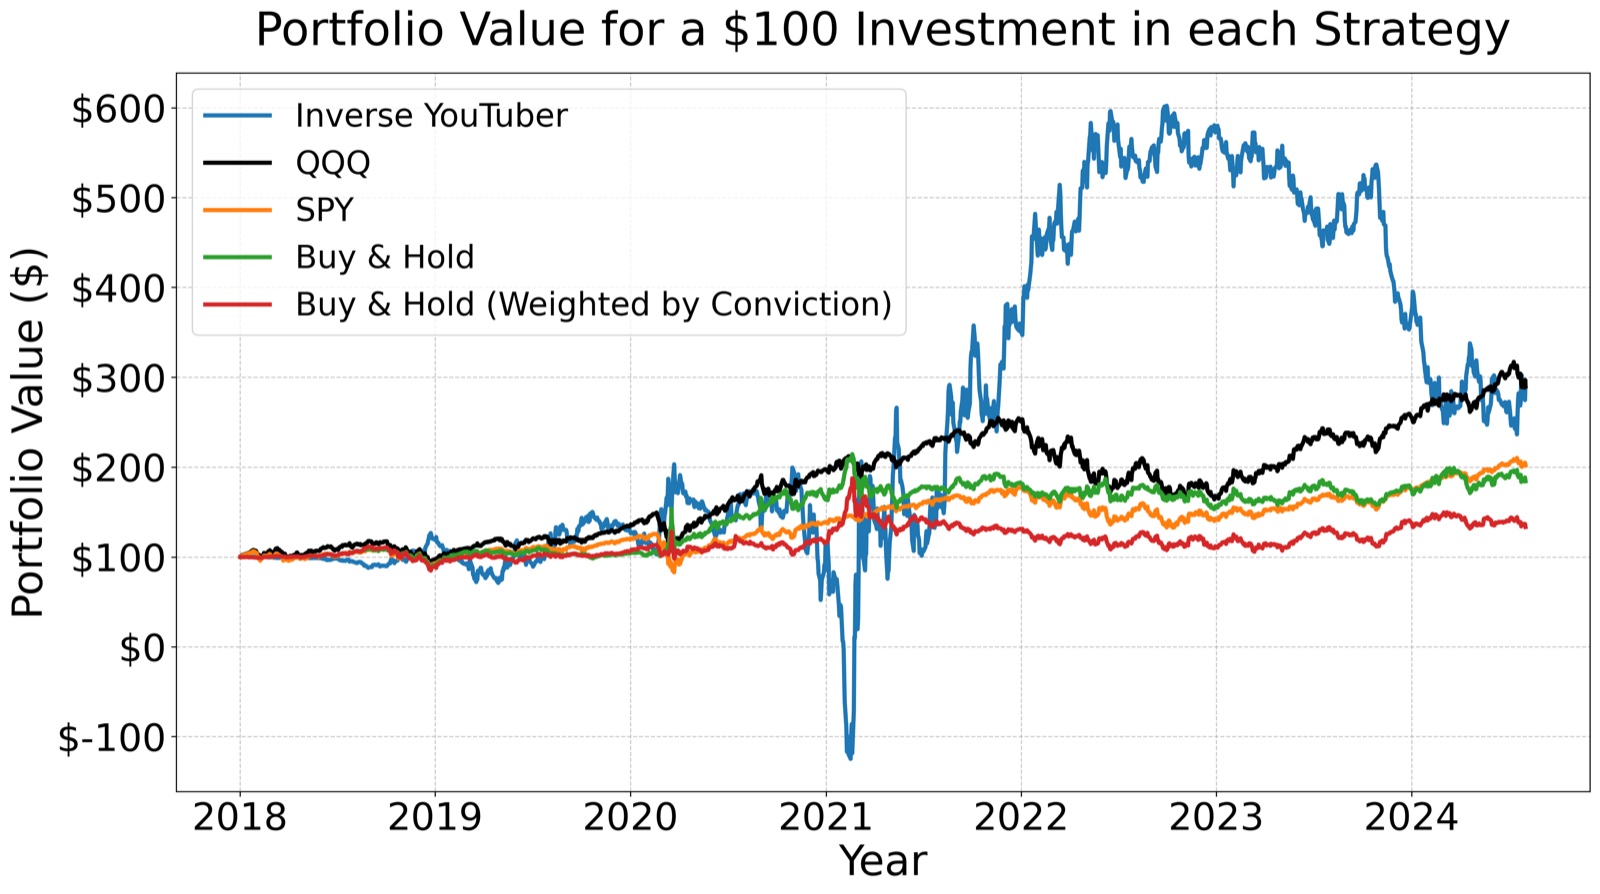
VideoConviction: A Multimodal Benchmark for Human Conviction and Stock Market Recommendations

Michael Galarnyk*, Veer Kejriwal*, Agam Shah*, Yash Bhardwaj, Nicholas Watney Meyer, Anand Krishnan, Sudheer Chava

A benchmark of 288 finfluencer videos (43 hours, 6,000+ expert annotations) that asks which stock is recommended, what action is advised and how strongly the speaker believes it. Across 16 LLMs and 6 video MLLMs, ticker extraction reaches 86% F1, but adding the action caps the best model at 54%, and adding conviction at 28%.

Selected Work

Projects

Independent Project 2026

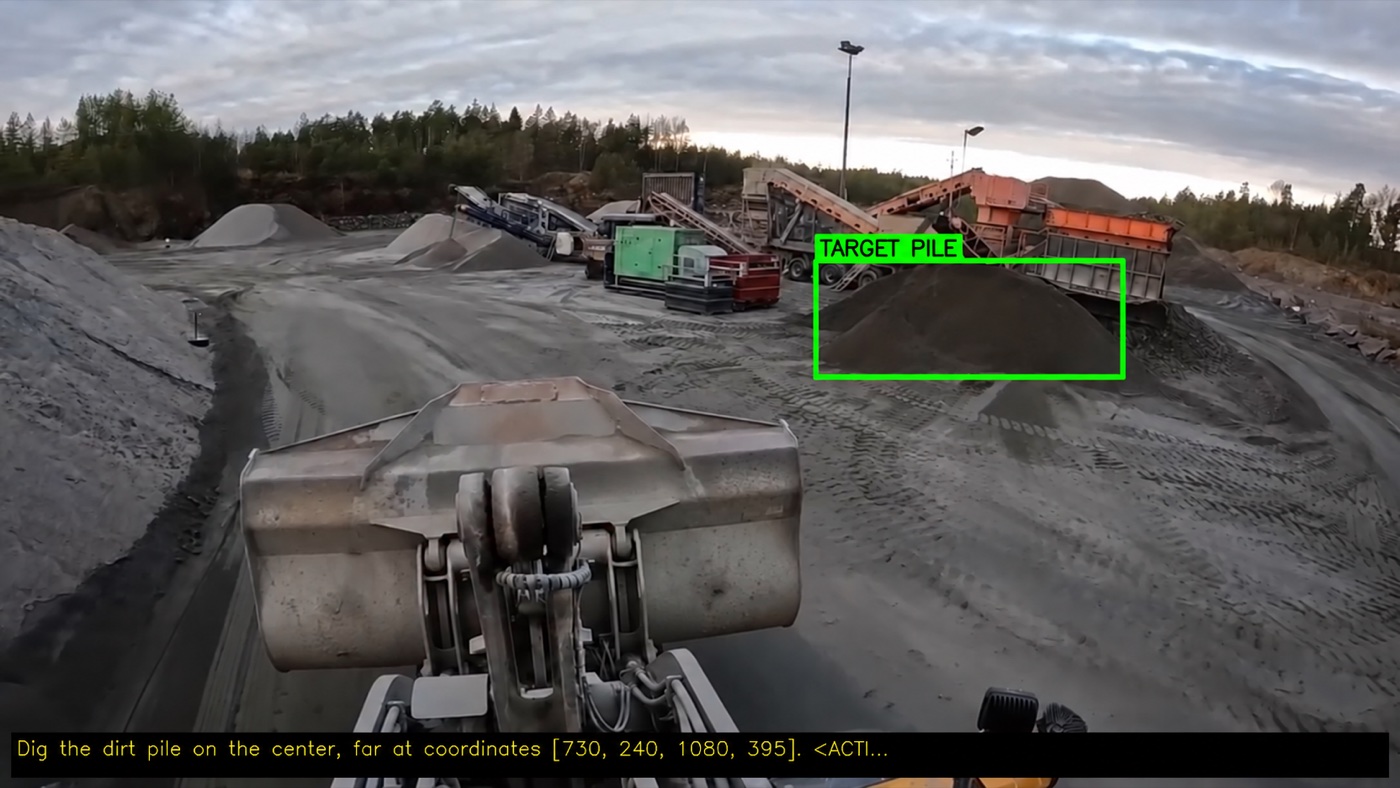
Tiny-VLA: grounded dig-target guidance for wheel loaders

Fine-tuned Qwen3-VL-2B with LoRA on a 4-bit base (17M trainable parameters, 0.8%) to tell a wheel loader where to dig: a target bounding box, its spatial position and a discrete action. Trained on 848 frames labelled automatically by a Florence-2 data engine, in about 10 GB of GPU memory.

Independent Project 2025

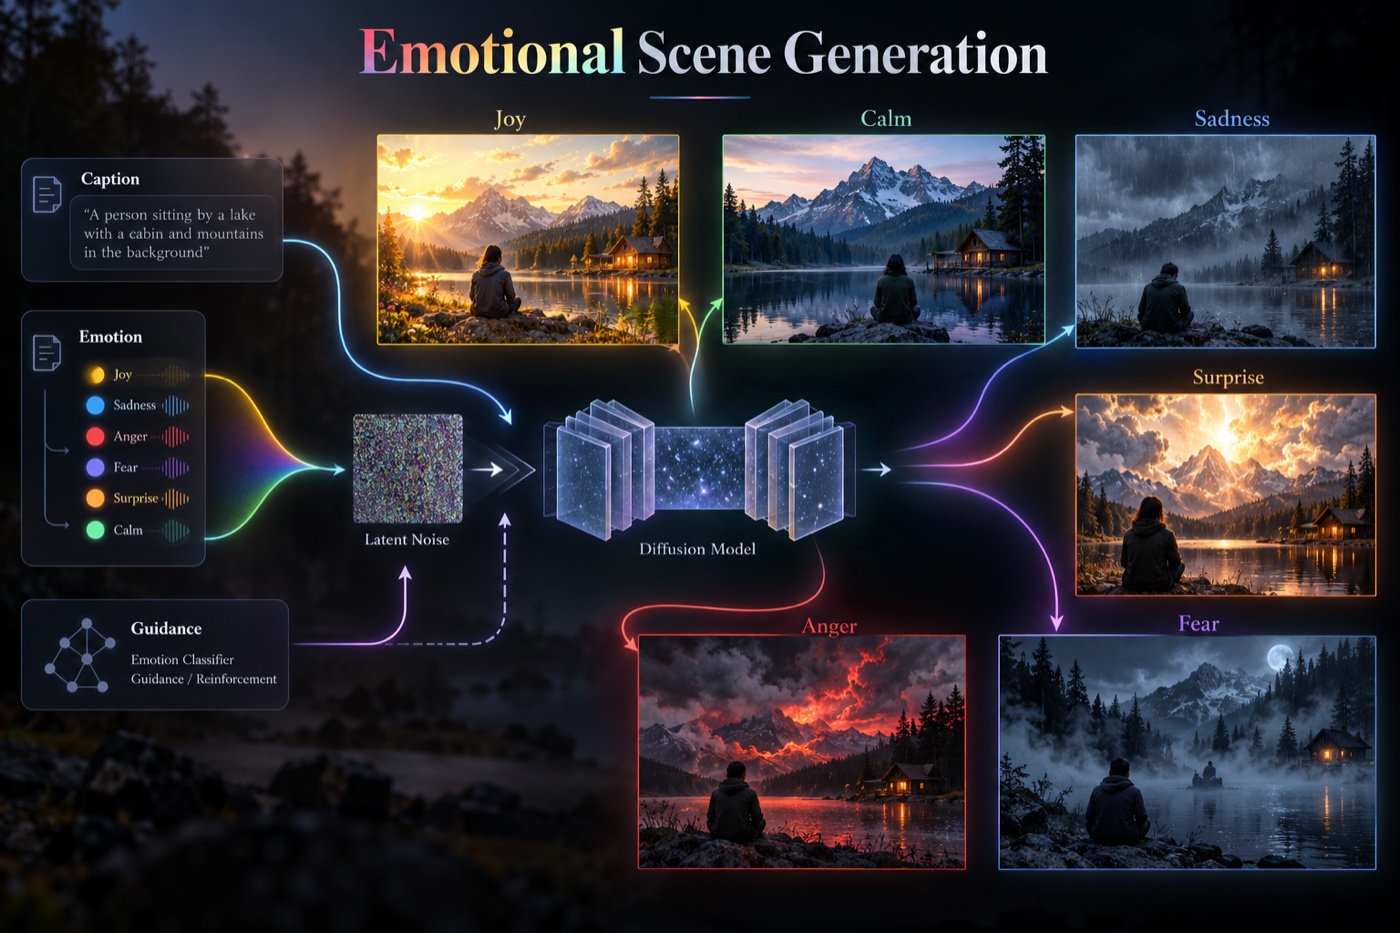
Emotion-conditioned image generation with Stable Diffusion

Fine-tuned Stable Diffusion 1.5 to generate images that evoke one of 8 emotions, on 100K images with LoRA (0.4% of parameters trainable): 15× faster training and 80% less memory than full fine-tuning. Compares learned emotion tokens, latent classifier guidance and multimodal conditioning.

Academic Record

Experience

Research Experience

  • Inria Paris, Willow team Apr 2026-Sep 2026
    Research Intern, advised by Cordelia Schmid and Shizhe Chen
    • Pretrained a Point Transformer V3 encoder with a query-based mask decoder on simulator-rendered scenes, so that each object token carries an instance mask, class, part-whole relation, articulation and cross-scene identity.
    • Plugged the tokens into 3D vision-language-action policies in place of dense point features, and benchmarked encoder-policy combinations on RLBench and RoboCasa.
  • Research Intern
    • VideoConviction (KDD 2025, oral): a benchmark of how well LLMs and video MLLMs read a speaker's conviction in stock recommendations: 288 finfluencer videos, 6,000+ expert annotations (457 hours).
    • FinCap (ICCV 2025 workshop): a benchmark for topic-aligned caption generation on financial short videos: 624 clips, 5 topics, all 7 transcript, audio and video combinations across 5 multimodal LLMs.
  • IIIT-Delhi, MIDAS Lab Jan 2021-Jun 2021
    Research Intern
    • Author profiling on the S2ORC corpus (600K papers, 160K authors) with graph neural networks (GNN-XML) and AnnexML.

Education

Industry

  • Urban Company Aug 2021-Mar 2025
    Software Developer 2, Bangalore. Promoted in 2023
    • Built dynamic platform fees on the checkout flow: over $6M a month in additional revenue.
    • Designed a distributed product-catalog cache (Kafka, Redis, MongoDB) for 27K products across 5 countries: 40% lower service latency, feeding the recommendation pipelines.
    • Deployed SARIMA and XGBoost dynamic pricing by demand and region: +4% revenue on $80M+ of transactions.

Teaching

  • Teaching Assistant
    BITS Pilani
    • Data Structures and Algorithms
    • Database Systems
    • Computer Programming

Skills

  • Tools Python, C++, PyTorch, Hugging Face (Transformers, Diffusers, PEFT, Accelerate), distributed multi-GPU training on SLURM clusters, MuJoCo, RLBench
  • LLM and VLM post-training Supervised fine-tuning, LoRA and QLoRA; RL and preference optimization (PPO, GRPO, RLOO, DPO)
  • Robot learning Vision-language-action policies, imitation learning, 3D representation learning on point clouds, world models and planning (CEM, MPC)
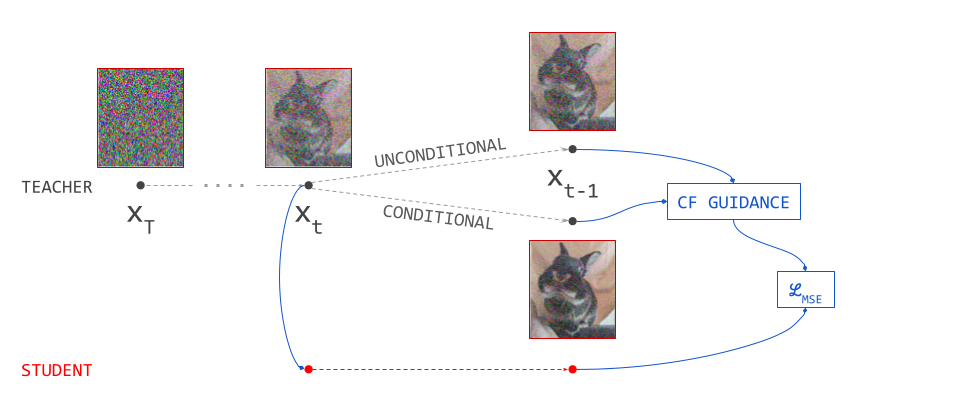
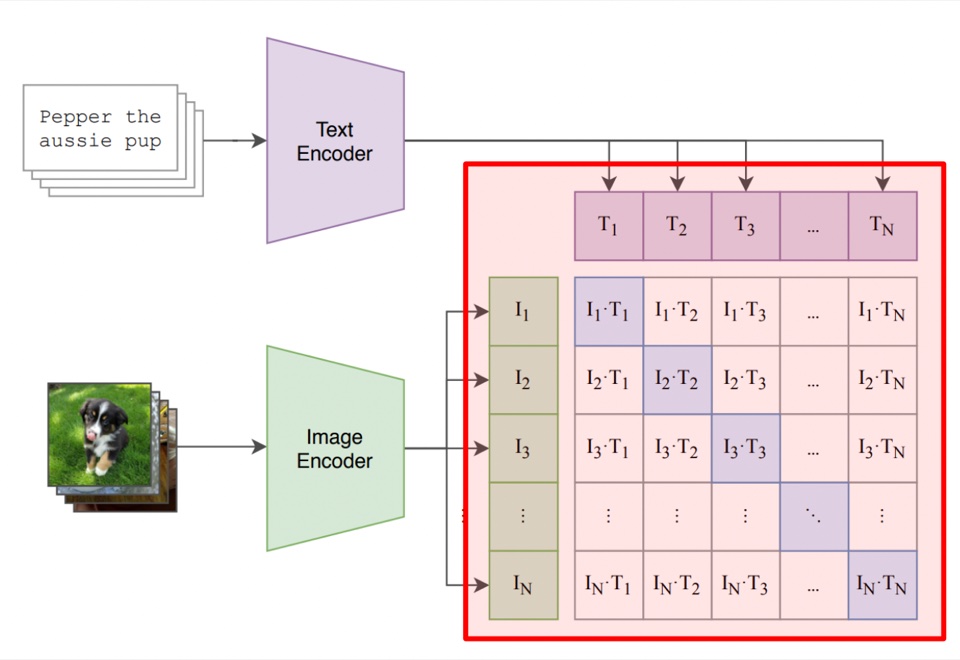
  • Generative and multimodal Diffusion models (distillation, classifier guidance), CLIP-style contrastive learning, multimodal LLMs
  • Evaluation and data LLM-as-judge benchmarks, simulator-rendered and VLM auto-labelled datasets, pre-registered experiments
Recognition

Awards