The question. Financial influencers on YouTube reach millions of retail investors, and much of what makes a stock pick persuasive is non-verbal: tone, confidence, facial expression. Can language and multimodal models tell what is being recommended, and how strongly the speaker means it?
What we built
- Data. 288 finfluencer videos from 2018 to 2024 (43 hours), cut into 687 recommendation segments.
- Annotation. 6,063 expert annotations over 457 hours: the stock ticker, the recommended action (buy, hold, don’t buy, sell, short sell, unclear) and a 1–3 conviction score judged from tone, facial expression and delivery.
- Tasks. Three nested extraction tasks, each on full-length videos and on segmented clips: ticker (T), ticker + action (TA), and ticker + action + conviction (TAC).
- Models. 16 LLMs on transcripts, including DeepSeek-R1 and V3, Llama-3.1 up to 405B, Qwen2.5, Claude 3.5, Gemini and GPT-4o, and 6 multimodal LLMs on the video itself: Gemini 1.5 and 2.0 (Flash and Pro), GPT-4o and LLaVA-1.6.
Results
- Tickers are easy, intent is not. The best F1 is 86.2% on T (Gemini 1.5 Flash on segmented video), 54.3% on TA (Gemini 2.0 Pro) and 28.2% on TAC (DeepSeek-V3).
- Video finds the stock, not the conviction. On TAC, a text-only model (DeepSeek-V3, 28.2%) edges out the best video model (GPT-4o, 27.9%).
- Segments beat full videos. Every task is easier on segmented clips; the best TAC score rises from 23.7% to 28.2%.
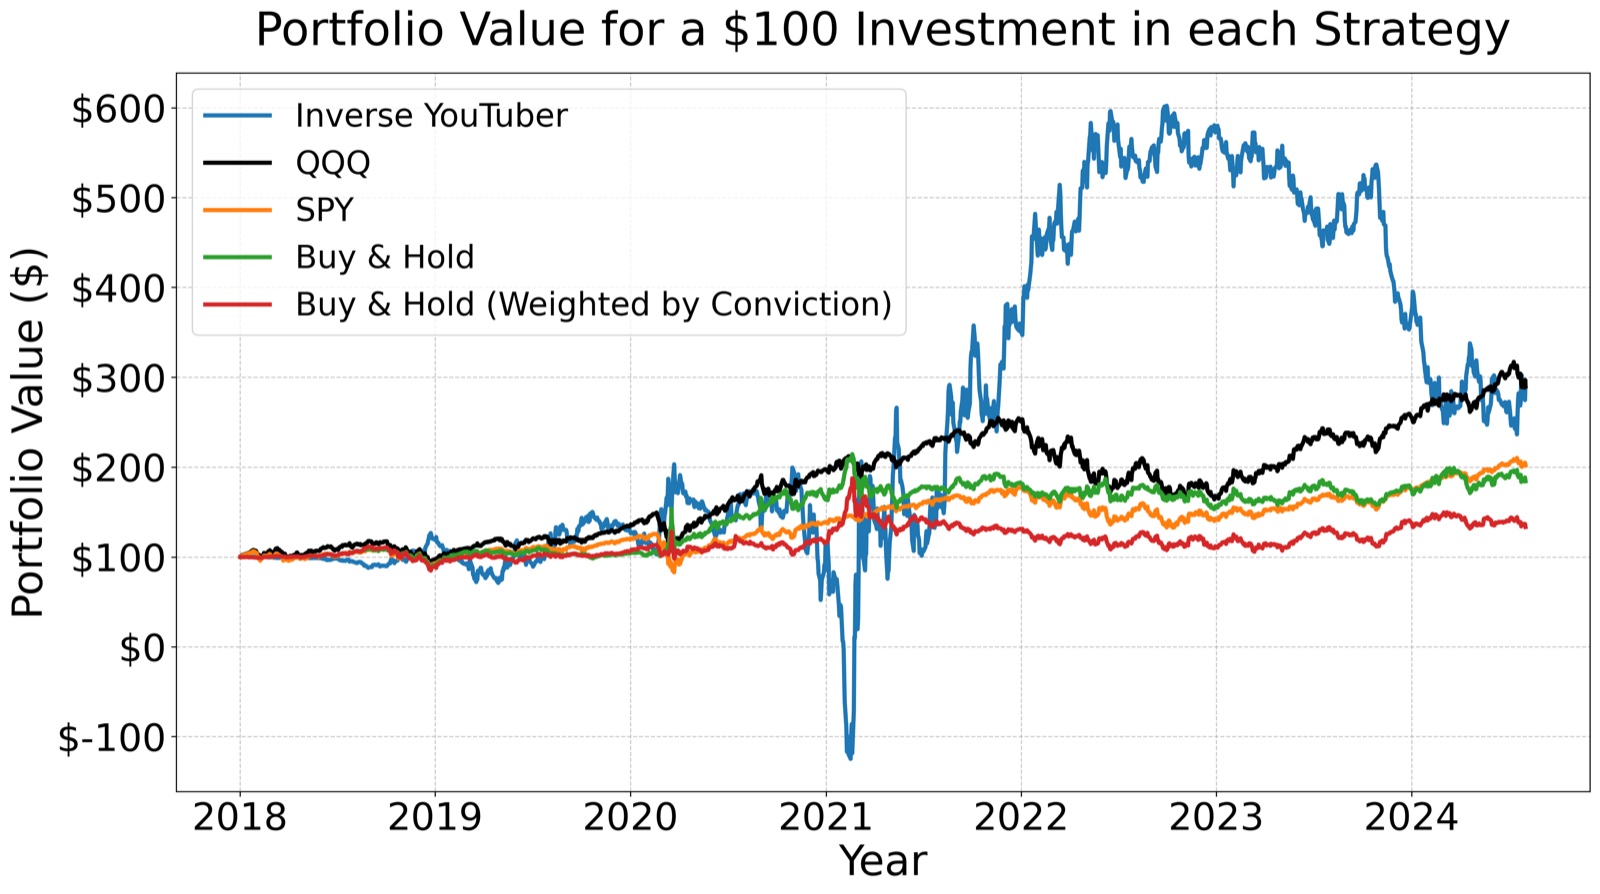
- Finfluencers lose to the index. In a back-test, high-conviction picks beat low-conviction ones but still trail the S&P 500. Betting against the finfluencers beats the S&P 500 by 6.8% a year, at higher risk (Sharpe 0.41 against 0.65).
My contribution
I worked on building the benchmark and on benchmarking the multimodal LLMs. The paper was presented as an oral at KDD 2025 in Toronto.
@inproceedings{galarnyk2025videoconviction,
  title     = {VideoConviction: A Multimodal Benchmark for Human Conviction and Stock Market Recommendations},
  author    = {Galarnyk, Michael and Kejriwal, Veer and Shah, Agam and Bhardwaj, Yash and Meyer, Nicholas Watney and Krishnan, Anand and Chava, Sudheer},
  booktitle = {Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining},
  year      = {2025},
  doi       = {10.1145/3711896.3737417}
}