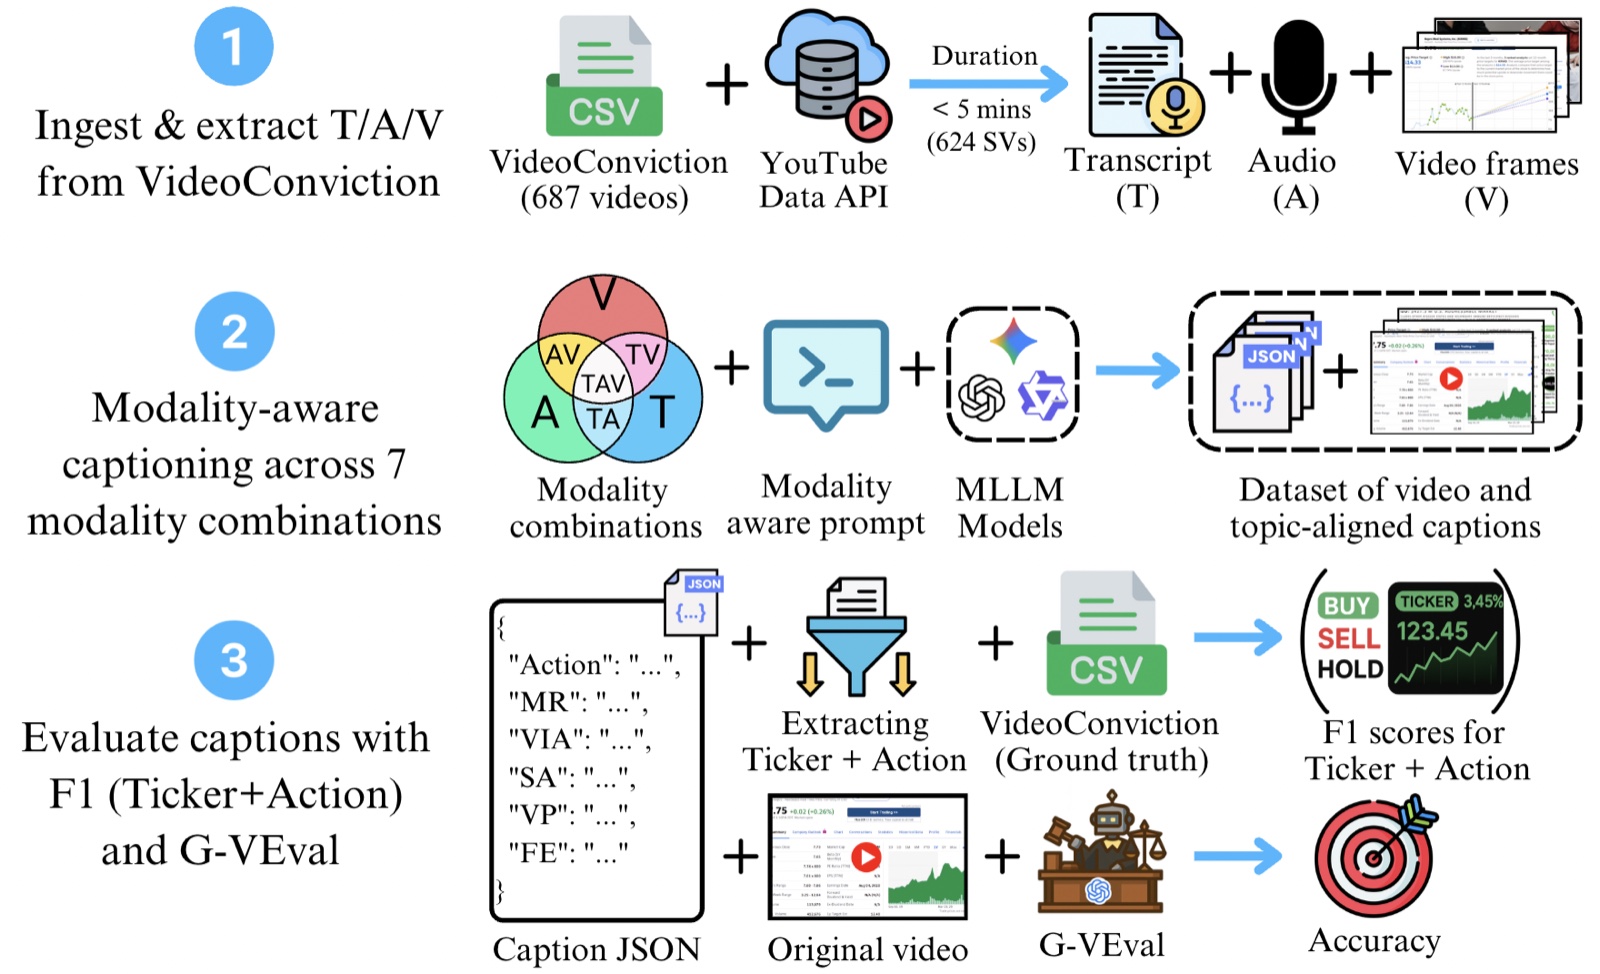
The question. Short financial videos carry much of their message visually: charts, on-screen tickers, gestures, emotion. When a multimodal LLM captions one, which inputs actually help, and does adding more of them always help?
What we built
- Data. 624 short-form financial YouTube videos (under five minutes, drawn from VideoConviction), with human labels for the recommended ticker and action.
- Inputs. Every non-empty combination of transcript (T), audio (A) and video (V): seven settings.
- Topics. Captions targeted at five topics: main recommendation, sentiment, video purpose, visual analysis and financial entities.
- Models and scoring. Gemini 2.0 Flash, Gemini 2.5 Flash, Qwen2.5-Omni-7B, GPT-4o mini and GPT-5 mini (the GPT models take no audio). Captions are scored by G-VEval, a GPT-4o judge with chain-of-thought reasoning; ticker and action extraction by F1.
Results
- Video alone is the best single input on 4 of 5 topics: 92% on visual analysis and 87% on financial entities (GPT-5 mini), 89% on video purpose (Gemini 2.5 Flash), and 82% on sentiment (GPT-5 mini).
- Some content only video can see. On visual analysis, transcripts alone score 14–51% across models; video alone scores 80–92%.
- More modalities is not always better. Pairs such as audio + video or transcript + video often beat all three together. The best main-recommendation score (85%) and the best ticker–action F1 (0.60) both come from Gemini 2.0 Flash on audio + video.
- The right input depends on the question. For extracting the exact ticker and action, video alone is the weakest input for every model.
My contribution
Co-first author. I developed the benchmark and ran the modality-fusion evaluations across the five models.
@inproceedings{sukhani2025fincap,
  title         = {FinCap: Topic-Aligned Captions for Short-Form Financial YouTube Videos},
  author        = {Sukhani, Siddhant and Bhardwaj, Yash and Bhadani, Riya and Kejriwal, Veer and Galarnyk, Michael and Chava, Sudheer},
  booktitle     = {ICCV 2025 Workshop on Short Video Understanding},
  year          = {2025},
  eprint        = {2509.25745},
  archivePrefix = {arXiv}
}